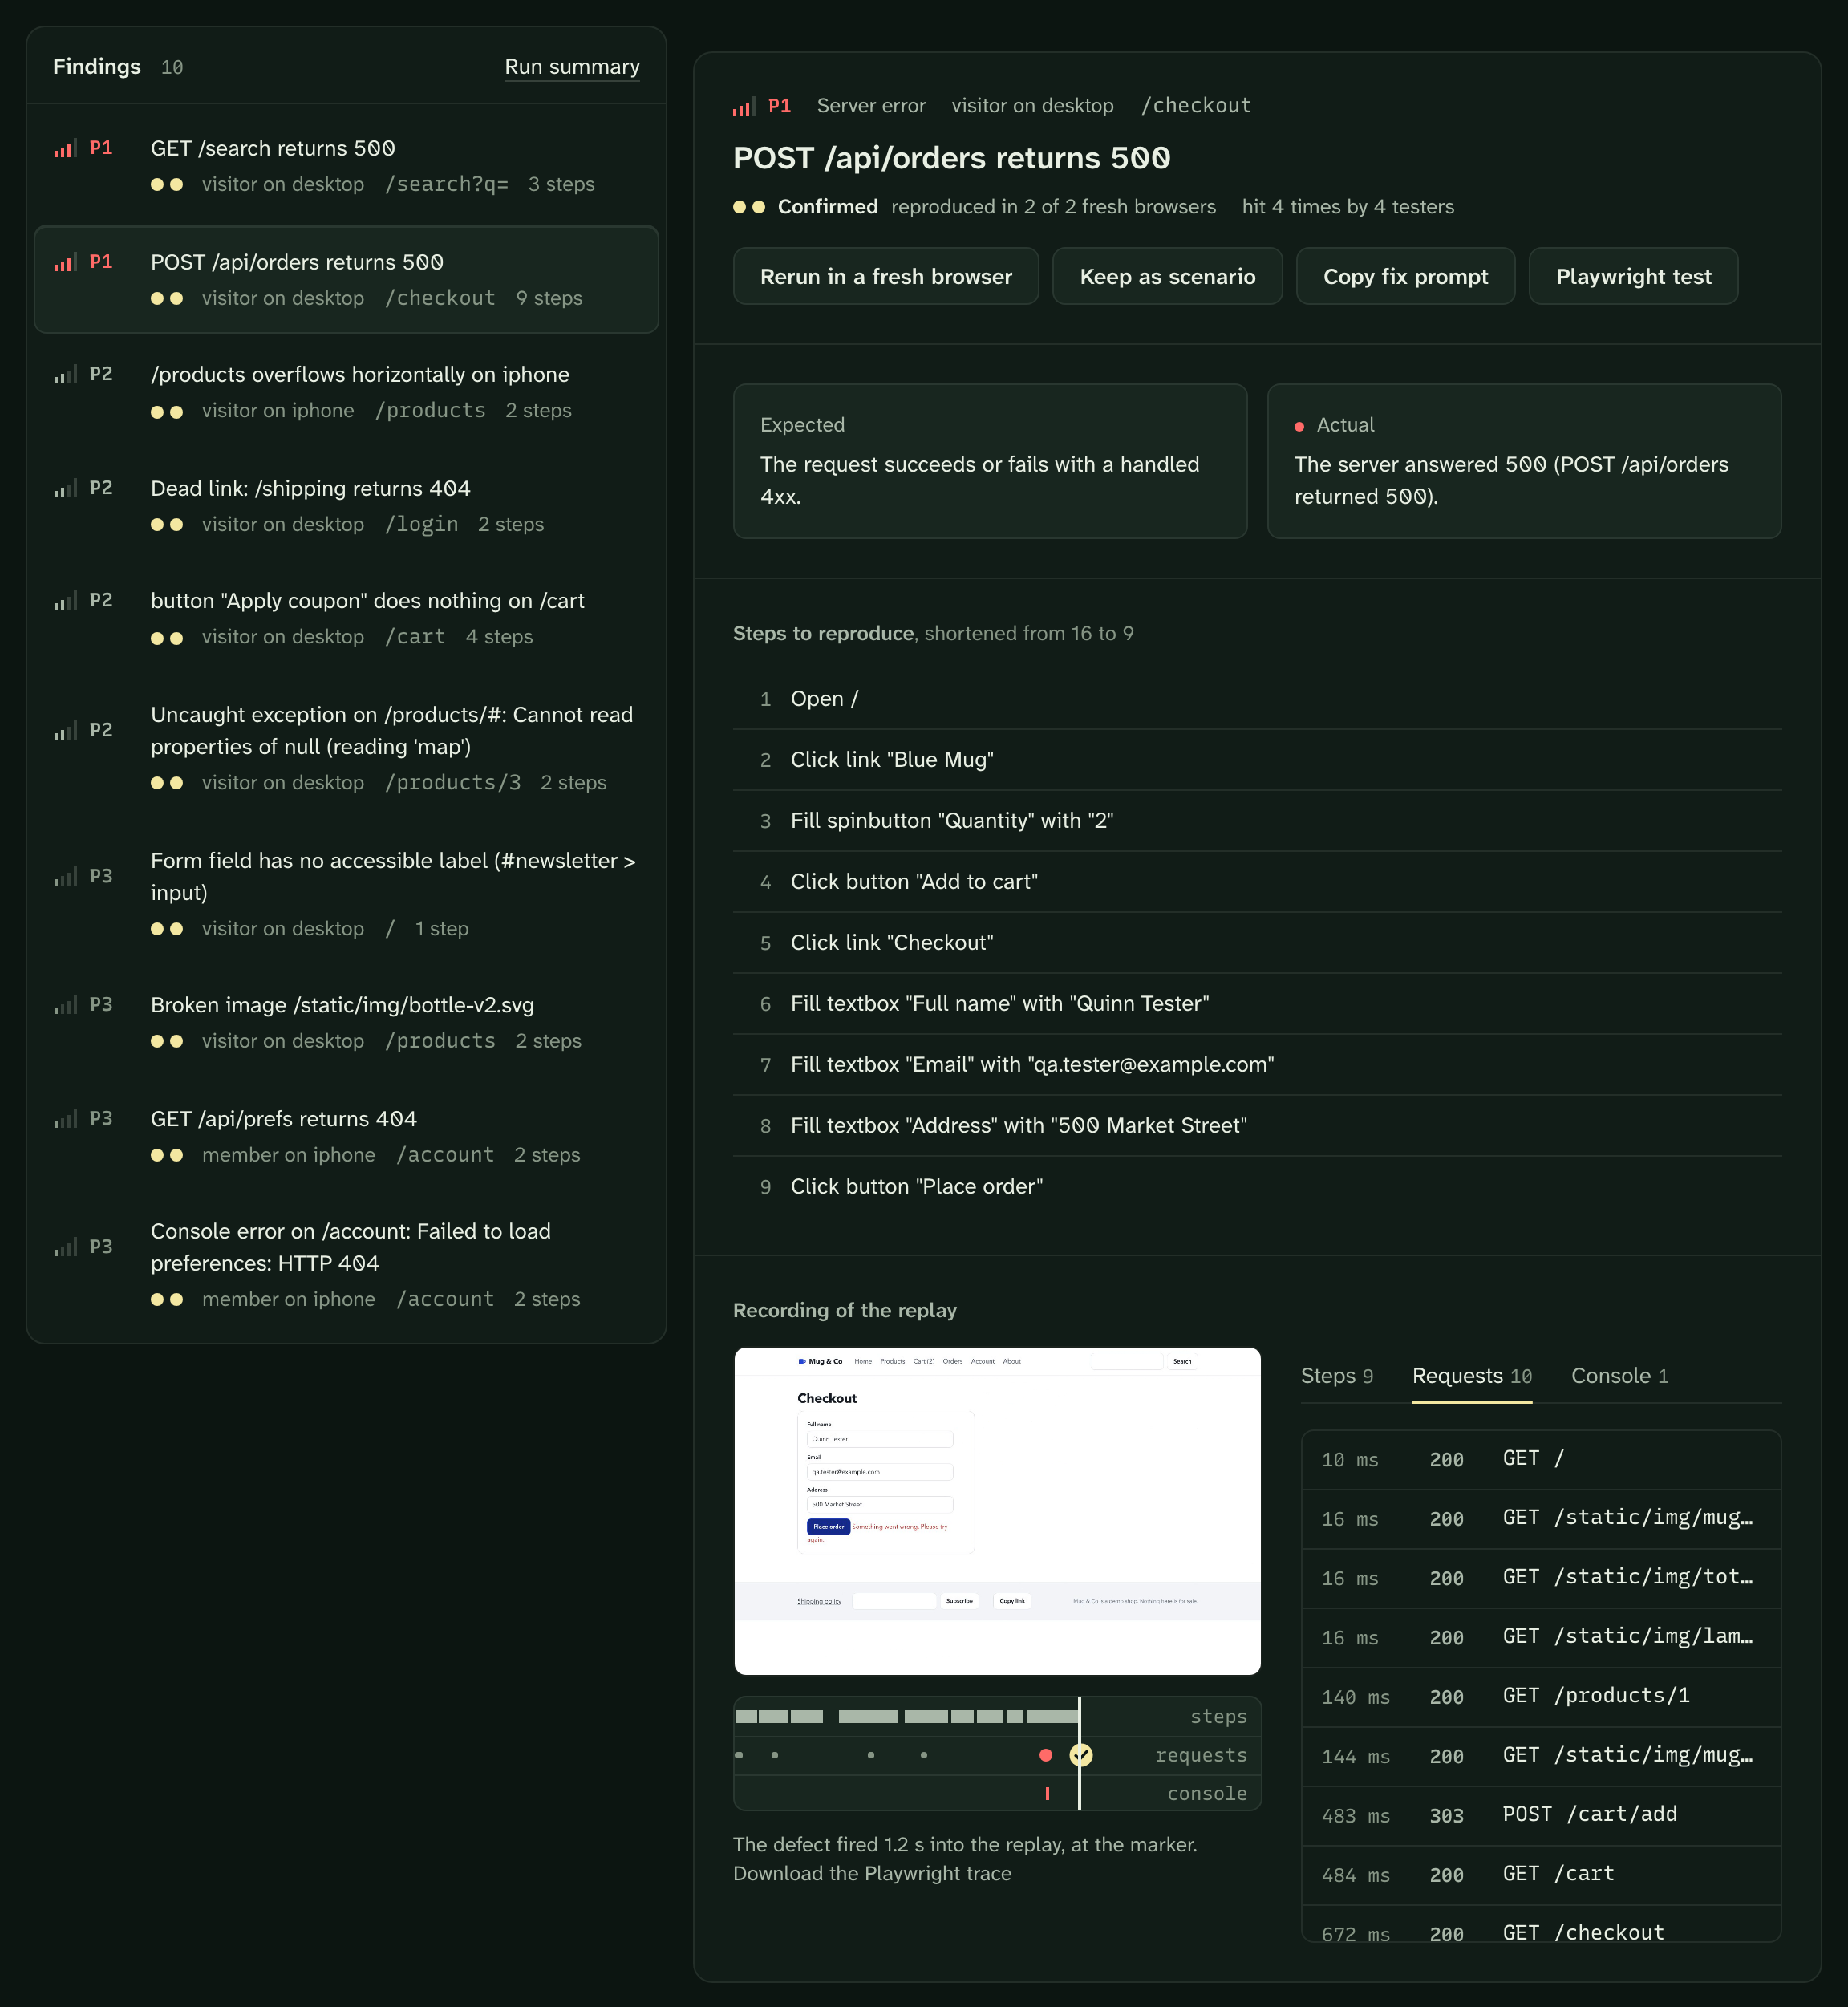
Catchbunny
Browser testers that prove a bug before they report it. A swarm of browsers explores a running web app, replays every suspect in a fresh browser, and reports only what happens again.
- Status
- Shipped
- Stack
- Python, asyncio, Playwright, FastAPI, SQLite, MCP, React
- Decisions
- Report a bug only if it happens again Catchbunny replays every suspect in a fresh browser. What does not repeat is dropped, and what does is cut to the fewest steps that still show it.
- Tests should outlive the model Catchbunny exports each confirmed bug as a regression test that replays with no model calls, so CI stays cheap and deterministic.
- Links
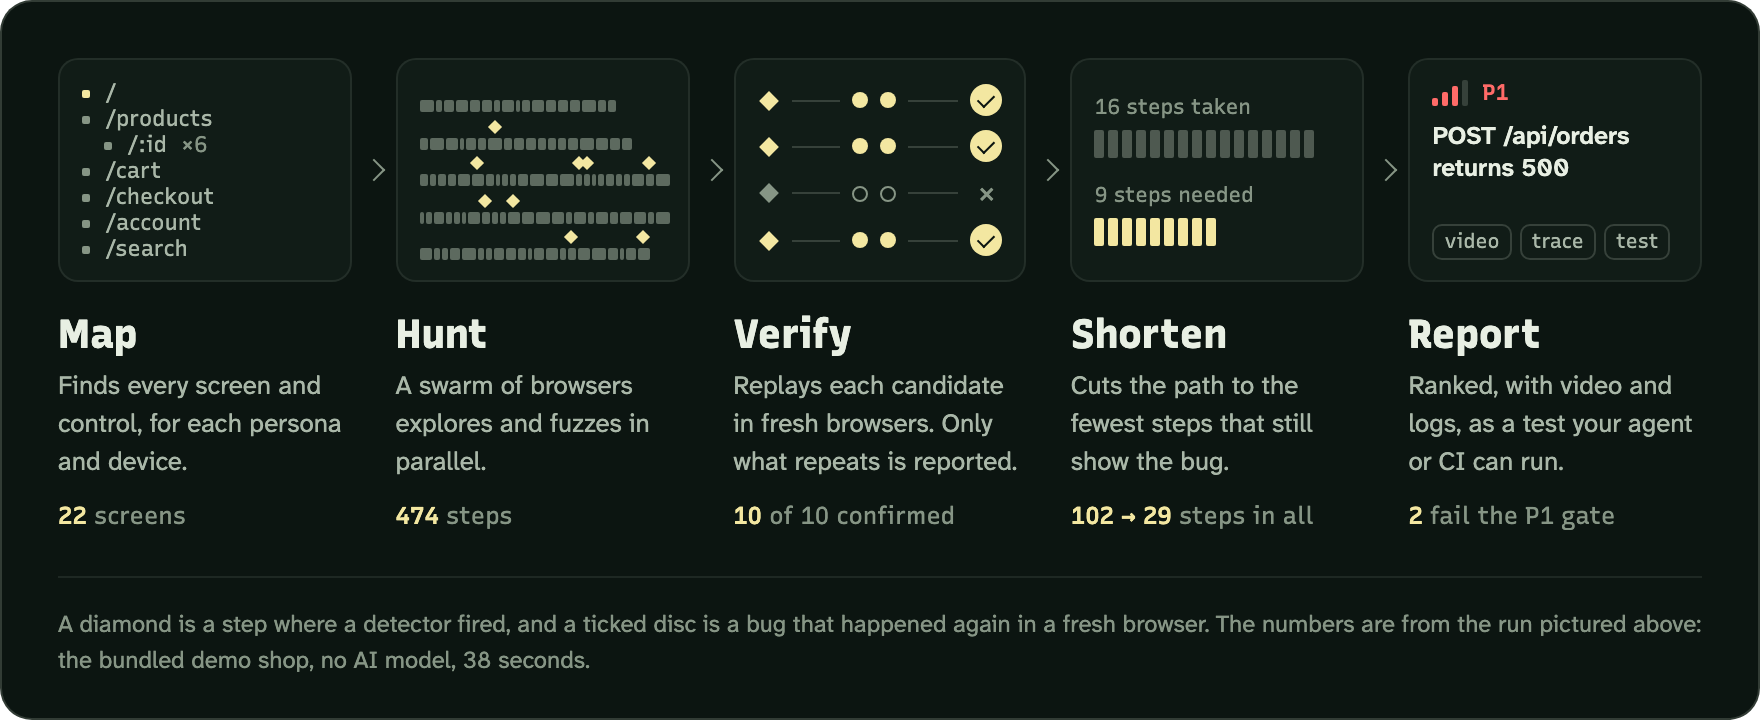
How a run works
- Map. Find every screen and control, for each persona and device.
- Hunt. A swarm of browsers explores and fuzzes in parallel.
- Verify. Replay each candidate in a fresh browser. Only what happens again is reported.
- Shorten. Cut the path to the fewest steps that still show the bug.
- Report. Ranked, with video and logs, and as a regression test your agent or CI can run.
Where it runs
- Nothing goes into the app under test. No SDK and no code; it opens the app by its address, the way a person would.
- One process serves the console, the HTTP API and the MCP endpoint on one port, so a scan a coding agent starts shows in the console as it happens.
- After
catchbunny connect, Claude Code or Codex can scan an app, read a finding, fix it and check the fix. - The testers need no AI. They explore and fuzz by rule. Claude or a local model through Ollama can drive them for bugs that raise no error.
Measured
On the bundled benchmark, a shop with planted bugs and traps that look like bugs, with no AI model:
| Result | What was measured |
|---|---|
| 9 of 9 | planted bugs that raise an error, found |
| 10 of 10 | confirmed findings are real, and none are reported on the fixed build |
| 78 → 28 | steps to reproduce, after shortening |
| 10 of 10 | exported regression tests fail on the buggy build and pass on the fixed one, with no model calls |
| 4.6× | faster with 8 testers than with 1 |
Two more planted bugs raise no error, so only a tester that understands the page can see them. With Claude Opus 5.5 driving the testers, one run confirmed both, for $0.75.